Done Is a Claim, Not a State: Building Evidence Gates for Coding Agents
A field guide to separating completion claims from attempts, readbacks, durable artifacts, and authorized transitions.
The first essay on this site had passed local checks. It had a pull request, a review record, and a specific revision ready to merge. Yet, immediately before the merge, one fact remained deliberately unresolved: deployment had not been verified.
It would have been easy to compress that situation into “the essay is done.” The sentence sounds harmless. Operationally, it collapses several different states into one: the source was written, checks had run, a reviewer had examined a revision, the change had not yet entered the default branch, and the publishing system had not reported what happened afterward.
That gap is the subject of this field note. “Done” is useful in conversation, but dangerous as workflow state unless the system can answer a more exact question: which transition is being requested, for which target and revision, on the strength of what evidence, under whose authority?
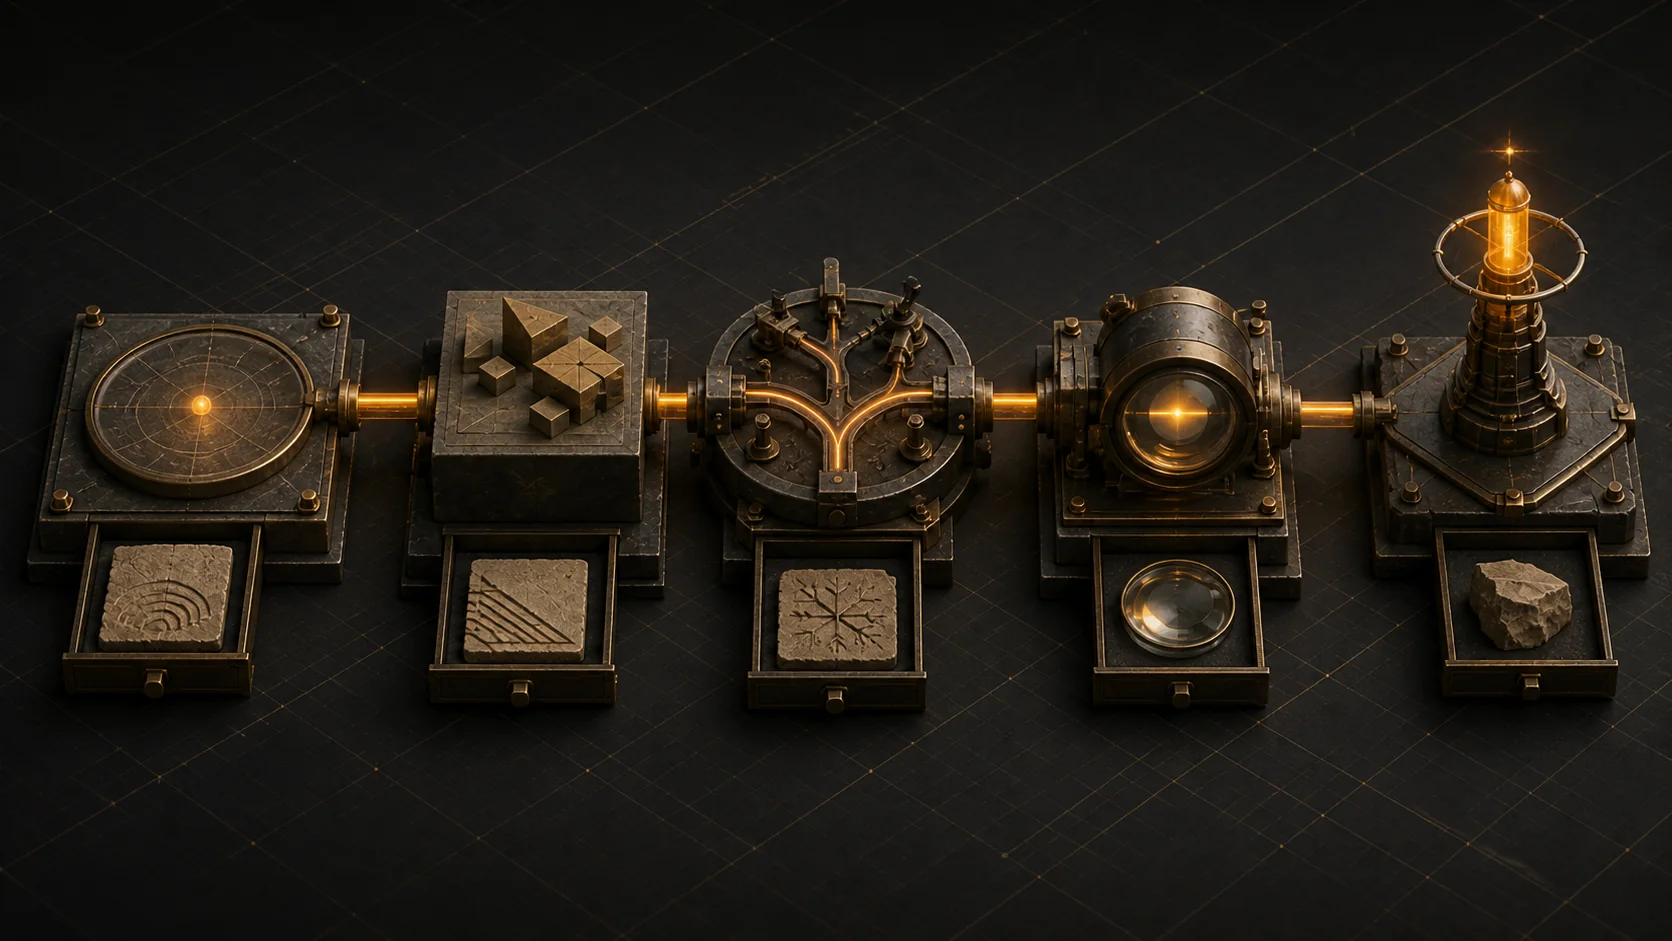
A five-part transition record
The following record is a practice-derived operating model, not a universal taxonomy or an externally validated standard. Its purpose is to stop narration from advancing system state. The five parts are related, but they are not a sequence of increasingly strong evidence. Authorization is a policy decision applied to the available evidence, while a durable artifact can preserve any of the other parts.
Claim
A claim names the bounded result someone believes is true: “the change is on the review branch,” “the checks passed for revision abc,” or “the site deployment completed.” A useful claim includes its subject. “It worked” does not.
A claim is necessary because evidence without a claim has no question to answer. It is not evidence merely because it is confidently stated, repeated by an agent, or formatted as a status report.
Attempt
An attempt is the action submitted to a target system: a file edit, a test command, a push, a review request, or a deployment trigger. Tool output that says an operation started can establish that an attempt occurred.
An attempt cannot establish the resulting state. A command can exit before a server records the change; a request can be accepted and later fail; an agent can call the correct tool with the wrong target.
Readback
A readback asks the target system what it now knows. Examples include reopening a GitHub issue, reading the remote branch SHA, querying a workflow run, or fetching the deployed route. This is stronger than trusting the action’s narration because it observes state after the attempt.
A readback still has boundaries. It can be stale, scoped to the wrong repository, or detached from the revision under discussion. The system identity, target identity, revision, and observation time belong with the result.
Durable artifact
A durable artifact makes the evidence inspectable beyond the current conversation: an issue, commit, pull request, check run, review record, validator receipt, or deployment record. Durability supports later review and comparison.
Durable does not mean true, complete, public, or permanent. Access-controlled evidence can be entirely appropriate. The requirement is that the authorized reviewer can inspect the artifact and bind it to the claim—not that sensitive traces should be published.
Authorization
Authorization answers whether the available evidence permits the requested transition. A passing build may authorize “ready for review” under one policy. It does not automatically authorize merge, production deployment, or a claim that users received the change.
This distinction is why the record is not a synonym for “collect more logs.” Evidence describes bounded observations. Authority applies a policy to those observations. Neither can substitute for the other.
An artifact autopsy
The first essay’s public delivery chain offers a neutral specimen. It is useful because the artifacts are inspectable and because no single artifact carries the entire story.
Research issue
Research issue #1 is a durable record of the question, sources, alternatives, and recommendation that preceded the essay.
It proves: GitHub records a closed research artifact at that URL, with content available for inspection.
It cannot prove alone: that the research was complete, every source was correct, or the selected direction would be implemented.
Plan issue
Plan issue #2 turns the research direction into an implementation contract with scope, tasks, and acceptance criteria.
It proves: a durable plan exists and expresses an intended change.
It cannot prove alone: that the files were edited, the criteria were satisfied, or anyone authorized a later transition.
Delivery pull request
Delivery pull request #3 exposes the proposed diff and records its merge as commit 8c694865f7d0f34ea4925f1258e2f208fbee713d.
It proves: GitHub records an inspectable change that entered the default branch at that merge commit.
It cannot prove alone: that deployment occurred, that every relevant behavior was tested, or that the change was free of defects.
Review record
Review comment 5075151889 records an assessment of the reviewed revision and explicitly keeps deployment outside its verified scope.
It proves: a review disposition and its stated evidence boundary were recorded on the pull request.
It cannot prove alone: that the review was exhaustive, that its judgment was correct, or that the reviewed revision later became the deployed revision.
Pages workflow run
Pages run 30300942452 records a completed, successful deployment workflow for the merge revision.
It proves: GitHub recorded success for the configured Pages workflow bound to that revision.
It cannot prove alone: that every route communicates the intended meaning, that every client can reach it, or that the site will remain available indefinitely.
The chain matters more than any link. Research explains why. The plan bounds what. The pull request exposes the change. Review adds a recorded assessment. The deployment record reports a later target-system event. Keeping the links separate prevents one green artifact from silently inheriting claims it never tested.
The workflow vocabulary used here is also visible in the public evidence-gated-delivery repository at commit 2d1eb675cf21aec1b14eea8155a8d19079769441. That historical commit is the revision boundary for statements about behavior in this essay. Pull request #3 merged later and is not part of that snapshot.
The transition rule
Treat “done” as a guarded transition request:
advance(claim, target, revision)
only when required evidence is valid,
bound to that target and revision,
and accepted by the named authority.
The identity binding is not clerical detail. “The checks passed” is weaker than “these configured checks passed for commit abc in repository owner/name at time t.” A valid receipt for the wrong subject is not supporting evidence. A correct hash for the wrong artifact is not supporting evidence. A review of revision abc cannot silently authorize revision def.
A compact semantic proof ledger can travel with a handoff:
Claim: the bounded transition being requested
Target: the system and object expected to change
Attempt event: the action submitted to that target
Readback: the target state observed afterward
Durable artifact: the inspectable evidence location
Proof limit: what the evidence does not establish
Transition authority: who or what may approve the next state
Current bounded state: observed, partial, blocked, or authorized
The ledger is intentionally text, not a dashboard. Its value is semantic completeness: another person should be able to inspect the nouns, test the bindings, and disagree with the transition. It also makes overreach visible. If the authority is allowed to approve a review branch but not production, the evidence cannot expand that authority.
Every signal has a proof ceiling
A proof ceiling is the strongest claim a signal can support without importing additional evidence.
A deterministic validator proves that encoded predicates passed for the supplied inputs. It cannot prove that omitted requirements were satisfied or that the predicates capture the intended meaning.
A cryptographic hash match provides strong evidence that two byte sequences are identical, assuming the algorithm and compared inputs are correctly specified. It cannot establish that the bytes are correct, safe, current, or attached to the intended subject.
Continuous integration proves that configured jobs reported their recorded results for a revision. It cannot prove unconfigured behavior, exhaustive coverage, or the absence of environment-specific failure.
A target-system readback proves what that system reported at an observation time. It cannot prove a broader end-to-end outcome unless the observation actually exercises that outcome.
An independent review adds a separate assessment and can challenge shared assumptions. It cannot become semantic truth merely because the reviewer is human or uses a different model.
An LLM judgment is an assessment produced under a prompt, context, model, and harness. It may help find omissions or compare an artifact to a rubric. It cannot certify truth by fluency or confidence, and two judges can share the same bad premise.
An approval proves permission under a specific policy and scope. It cannot prove technical correctness, and approval for one transition does not authorize the next.
This bounded view is consistent with external guidance without claiming that the guidance validates this ladder. Anthropic’s discussion of agent evaluations separates evaluation design, environment state, trajectories, and outcomes. OpenAI’s coding-evaluation audit shows why the integrity of the evaluation environment matters to the result, while its harness engineering report describes repository knowledge, mechanical enforcement, and feedback as parts of the surrounding system. These sources support bounded inspection of the harness; they do not establish personal outcomes or make any single evaluation conclusive.
Honest non-success states
Evidence gates are most useful when they improve the vocabulary between “working” and “done.”
- Missing: required evidence was not produced or cannot be resolved.
- Partial: some required predicates passed and others remain unverified.
- Stale: the evidence predates a relevant change, exceeds its observation window, or has been superseded.
- Mismatched: the artifact belongs to the wrong target, revision, identity, or claim.
- Unauthorized: the evidence may be valid, but no permitted authority approved the transition.
- Invalidated: later readback contradicts the earlier state or the authority was revoked.
These labels are not exhaustive. States such as started, failed, unknown, blocked, and rolled back remain useful when they describe an observable condition rather than substitute for one.
Consider three illustrative examples, not reports about the public delivery chain. First, a validator receipt is structurally valid but names another repository: right receipt, wrong subject. Second, a hash matches a generated archive while the policy requires the source commit: right hash, wrong artifact. Third, a schema accepts every required field while the prose reverses the intended policy: schema-valid, meaning-wrong. Each example contains real evidence. None supports the requested claim.
The honest response is not to discard the evidence. It is to lower the state to the strongest defensible description—missing, mismatched, partial, stale, unauthorized, invalidated, or blocked—and name the next observation needed.
The goal is not to maximize gates. It is to make greater autonomy reviewable. When an agent can continue in a cloud sandbox after the initiating device disconnects, target and revision bindings let another person inspect what happened without depending on the initiating engineer’s laptop, memory, or narration. Evidence becomes part of the shared harness that allows remote and parallel work to scale without scaling ambiguity with it.
Use the field check at handoff boundaries, not only at the end of a large project. A branch push can be verified while merge remains unauthorized. A merge can be verified while deployment remains unknown. A deployment workflow can succeed while the meaning of a route still needs direct inspection. Precise incompleteness is more useful than premature closure.
Source notes
- The public site chain consists of research issue #1, plan issue #2, delivery pull request #3, review comment
5075151889, and Pages run30300942452. Their individual proof limits are stated above. - Workflow references are bound to the historical
evidence-gated-deliverycommit2d1eb675cf21aec1b14eea8155a8d19079769441. Pull request #3 merged later and is outside that snapshot. - Anthropic, “Demystifying evals for AI agents”. The article informs the evaluation context above; it does not validate the practice-derived transition record.
- OpenAI, “Separating signal from noise: An audit of SWE-bench Verified” and “Harness engineering”. These reports support attention to evaluation integrity and the surrounding engineering system; they do not prove personal delivery outcomes.